
You can ship a working internal tool this week without ever handing a stranger your production deploy key. The agent runs on your own machine, edits your repository, and stops cold at the deploy button unless a human presses it.
You already have the Cursor tab open. What nobody handed you is the part that decides whether this goes well: what to give the agent first, and when to say no.
The agent is rarely the bottleneck. The one-page brief, the locked production key, and the diff review are. Skip any of them and a clean demo turns into a Friday-night mess you cannot untangle.
The agent executes exactly the scope and the checks you define, nothing more. So the workflow holds regardless of vendor: brief, permissions, small reviewable passes, a hostile test, gated promotion. Pick one internal task, write a one-page brief with 12 numbered acceptance checks, and run a single reviewable pass – no production access, no exceptions.
What the agent actually does
You're handing it a program that runs on your machine and touches your files, not a chat box that hands back snippets.
A chat assistant returns code in a window and waits for you to paste it somewhere. A coding agent such as Cursor or Claude Code sits inside your repository on your laptop: it reads the file tree, edits several files in one pass, runs the test command, and opens a pull request when it finishes. That is the entire difference, and it is not a small one. Picking which tools survive daily use is its own discipline, and the AI tools worth keeping covers what earned a permanent spot.
The loop it runs is plan, act, observe, correct. The observe step carries all the weight. The correction comes from output the agent actually ran — a failing test, a stack trace, a query that returned zero rows — not from its own confidence about the code.
This is the common mistake. With no test command and no clear success check, observe has nothing to read.
It then fails silently. The broken diff looks exactly like a finished one: same file count, same tidy commit message, same cheerful summary at the end. Nothing in the transcript signals the gap, because there is no gap as far as the agent can tell.
What stays with you never changes. Scope, production access, and the final review are yours. The agent never holds the deploy key, never approves its own pull request, never decides the build is done well enough to ship.
Split it cleanly: the agent supplies speed and file edits. You supply the definition of done and the judgment that it was met.
💡 PRO TIP
Always give it one command
Before the first prompt, wire up a single command that runs every check in your project. The agent decides what to do next by reading the output of that command, so a missing command means it invents its own idea of finished.
What should I have it build first?
The loop only corrects against a check you hand it, so pick a task with a finish line you can see from across the room.
For a two-person design studio, that is a five-screen client and project tracker replacing the spreadsheet that currently runs the business, built on Next.js, Supabase, and Vercel. The old file gets retired, the CSV import pulls the existing rows across, and the twelve acceptance checks pass. Nothing more ambitious than that on the first job.
Skip the multi-tenant marketplace, the billing system, anything that touches customer production data. Those have no visible edge, failures cost real money, and you cannot verify them yourself without building half the thing twice. Each week of agent time spends against a finish line you cannot confirm.
Choose a task where you already know the workaround by hand. You spot a wrong client total in four seconds because you have fixed that same formula by hand for two years. That reflexes-level knowledge is the review capacity the agent leans on, and you cannot fake it on an unfamiliar domain.
Hold the scope at five screens, three user roles, one CSV import. Small enough that any diff in the build fits in a single read on a laptop screen without scrolling twice.
Write the brief the agent cannot misread
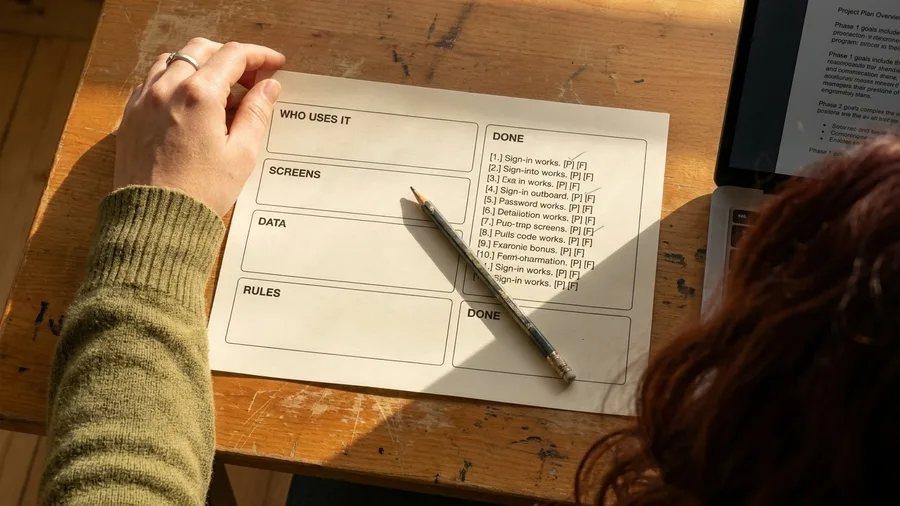
Without a written brief, the agent fills every gap with its own assumptions, and every one of those is a feature you will be reviewing on Friday afternoon.
Keep it to one page and five fields: who uses the app, what screens they touch, what data moves through it, what rules constrain it, and what counts as done. For the studio tracker that is five screens, three roles, one CSV import, and twelve acceptance checks. Number every check, one through twelve, so each can be marked pass or fail on a printout rather than argued about in prose.
Write the out-of-scope list explicitly, in its own block: no billing, no notifications, no mobile app. The agent treats silence as an invitation and builds the thing you did not ask for. That feature shows up in the diff and costs you a twenty-minute review you never budgeted.
State the data rules as rules, not wishes. Which of the three roles sees which client records, and what happens when a CSV import hits a malformed row. The answer must be: bad rows rejected with a reason, nothing partially written to the database, existing records untouched.
Then require the agent to restate the plan in its own words before it writes a line of code. That restatement surfaces a misread role or a misread screen while the fix is a sentence edit rather than a rewrite of four files.
The numbered acceptance checks are your definition of done made machine-readable, and they are the only stable target the agent has.
🧱 The build, one reviewable pass at a time
Schema
Agent writes the tables, roles and relationships; you read the migration file before anything renders.
One screen
Agent builds a single screen against the schema; you load it and click every control.
That screen's test
Agent writes and runs the check for that screen only; confirm it fails when you break a field on purpose.
Commit
Commit the slice so any later pass can be reverted alone without touching working code.
Repeat for five slices
Same three moves per screen, roughly 45 minutes of agent work each, with a human diff read between.
CSV import last
The riskiest piece runs once the rest of the tracker is stable and you have a backup to restore from.
Give it the tools and permissions it needs
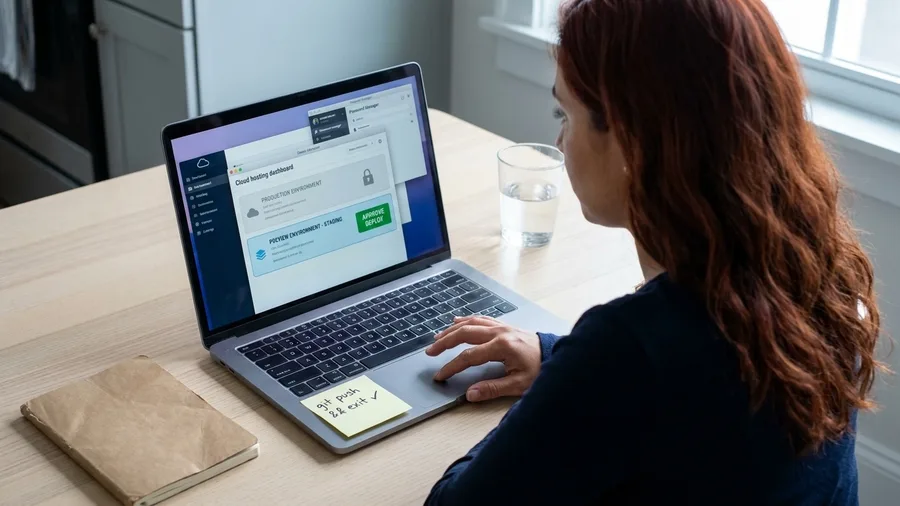
The agent can only hit the brief on the apps it can actually reach, so access comes next. Grant it five things and nothing more: local repository access, the environment variables the build reads, one test command, the Supabase project, and a Vercel preview target. That is the whole menu.
Then withhold the one key that matters. Production deploy keys stay in your password manager, and the tracker never touches real customer data until it has earned that. Promoting a preview build to production is a single human approval click in the Vercel dashboard, and the agent cannot press it.
Skip the running environment and you get the quiet failure: an agent that never executed the app writing code that looks finished and was never tested once. You review fifty lines and cannot tell which were verified and which were imagined.
Point every secret at one place, a single .env.local file the agent reads, and define one command, npm run verify, that runs lint, typecheck and the full test suite together. Then "did it work" has one answer instead of an argument about which terminal window to trust.
Every line of access is a bet on what the agent can prove by running versus what you have to verify with your own hands. Grant the checkable, lock the irreversible.
What the agent gets, and what it never gets
Grant it
- Read-write on the local repo, never the remote main branch
- Only the env vars listed in .env.local, nothing global
- Run npm run verify before any review request
- Supabase project scoped to a staging schema
- Open pull requests; merge stays human
Withhold it
- Vercel production deploy token
- Any connection string with live customer rows
- The Vercel Approve button in the dashboard
- Direct schema edits; require a migration file first
- Adding packages without a signed-off package.json diff
Run the build in small reviewable passes
Volume is the last big risk once access is scoped and production is locked: a diff of 400 lines is unreviewable even when it runs clean. Break the work into vertical slices.
Take one slice at a time: the schema change first, then the screen that reads it, then the test that covers both. Aim for passes of roughly 45 minutes and commit after each one, so a bad slice reverts on its own without dragging the good work behind it.
Read the diff before you type the next prompt. If the agent touches files outside the slice, stop, revert, and restate the slice in one sentence. Chasing an expanding change set is how a clean build turns into a mess you cannot untangle at 11 p.m.
Pace it realistically: 6 to 8 hours of agent work across two weekends, plus about 2 hours of human review. The human hours are the real constraint; the agent will happily keep going, but you cannot read faster than you read.
Print a stop list and tape it above the desk: no new dependencies without your approval, no schema changes without a migration file, no production deploys from the agent, ever. The diff is the unit of judgment, and a pass too big to read was scoped too big.
Score the build before you trust it
Test it like a hostile user
The agent's own tests prove it followed your instructions; they cannot prove the app is safe. Walk all 12 acceptance checks yourself and mark each one pass or fail in a plain text file.
Start with the CSV import. Feed it a file with missing columns, then one with duplicate rows. Watch the rejected rows come back with a reason attached to each, and confirm that a failed import leaves the existing client records exactly as they were, nothing half-written into the database.
Then attack the roles. Log in as the restricted user, paste a client record URL straight into the address bar, and hit the underlying query path outside the UI. A record the role should not see must return nothing, not a polite error above the visible data.
Check the boring edges too: empty states with no projects yet, a refresh after an edit that should still show the change, and an export or backup that pulls real rows out before anyone trusts the tracker with live client work.
This is the part that cannot be handed off. The agent's tests share the agent's blind spots, so the person actively trying to break the app is the only real check it ever gets.
What the first six weeks actually look like
Ship it, then decide what to maintain
Promotion to production is a human click, not an agent command. Only after all 12 acceptance checks pass under your hostile testing does the Vercel preview earn a production deploy – and the person who promoted it should be able to say which checks they ran and what failed first. Lock the deploy key away from the agent's reach for the entire build; the agent never holds it, not once the tracker looks finished. Set the domain, then confirm Supabase backups are actually running with a restore you have tested, not a green dashboard badge you glanced at.
Name one person who owns fixes, not 'the team'.
One name goes in the brief, or nobody answers the first broken CSV import on a Monday morning. That owner is the person who gets the Slack message when a row lands in the wrong client record at 9am, and they need the Supabase login and the Vercel project before that happens, not after. Budget the running cost plainly: $20/month for the coding agent, $25/month for Supabase Pro plus $20/month for Vercel Pro – $65 monthly – and $15/year for the domain. Put those numbers in the same document as the acceptance checks so the build has a real bill attached.
Then decide what not to maintain. No custom analytics dashboard, no extra screens beyond the original 5, no automation until the studio has actually used the tracker for a full billing cycle. Every feature you skip is a fix you never owe, and a two-person studio has no capacity for maintenance debt on software nobody asked for. Shipping, in the end, is a decision about who owns the thing and what it costs to keep – a judgment call the agent cannot make, because it has no stake in the answer.
⚠️ COMMON MISTAKE
Do not buy a year of anything yet
Pay monthly on Supabase and Vercel until the tracker has survived a full month of real studio work. A failed first build costs you $65 and a weekend, not a $780 annual commitment to a stack you may drop.
Frequently Asked Questions
Do I need to know how to code to use an AI coding agent?
You need to read code well enough to catch a wrong query or a missing permission check, not to write it from scratch. Start with a stack you can inspect locally, and require the agent to explain each diff in plain sentences before you approve it.
Will the agent deploy to production on its own?
Only if you let it. Keep production deploy keys out of its environment and require a human approval click in your host's dashboard to promote a preview build. This one gate prevents the majority of costly agent mistakes.
How long does a first agent build actually take?
The example here — five screens, three roles, one CSV import — runs 6 to 8 hours of agent work across two weekends plus about 2 hours of human review. The human hours are the real constraint; adding agent hours does not shorten review.
What if the agent writes code I cannot understand?
Revert the pass and restate the slice in smaller terms. A diff you cannot read was scoped too big, and approving it turns your codebase into something no human can safely change.
Do the agent's own tests count as proof the app works?
No. They prove it followed the instructions it was given. You still walk every acceptance check by hand and try to break the permissions yourself, because the agent's tests share the agent's blind spots.
What does this stack cost to keep running?
Roughly $65/month — $20 for the coding agent, $25 for Supabase Pro, $20 for Vercel Pro — plus about $15/year for the domain. Stay on monthly billing until the build has proven itself over a month of real use.
One spreadsheet, one brief, one reviewable pass
The workflow that repeats is the one just walked: a one-page brief with acceptance checks, permissions with production locked, 45-minute review slices, a hostile test against all 12 checks, then a human-gated promotion. None of it changes if you swap Cursor for Claude Code tomorrow.
Agents build exactly what the brief, the permissions, and the checks allow. That is why a five-screen client and project tracker ships in two weekends plus two hours of human review, and why a marketplace does not – the checks would run past 12 and the diffs past one screen.
So go back to the half-open editor with one decision: which spreadsheet do you replace first? Write the brief, paste the stop list into the agent's rules file, and let it run one small pass you can read start to finish.
Write the brief before you open Cursor
Five fields, 12 numbered checks, and an out-of-scope list. That page is what turns a fast literal builder into something you can actually ship.